Mirendil unveils Fern, its first model, pretrained from scratch with a context window of up to 10 million tokens

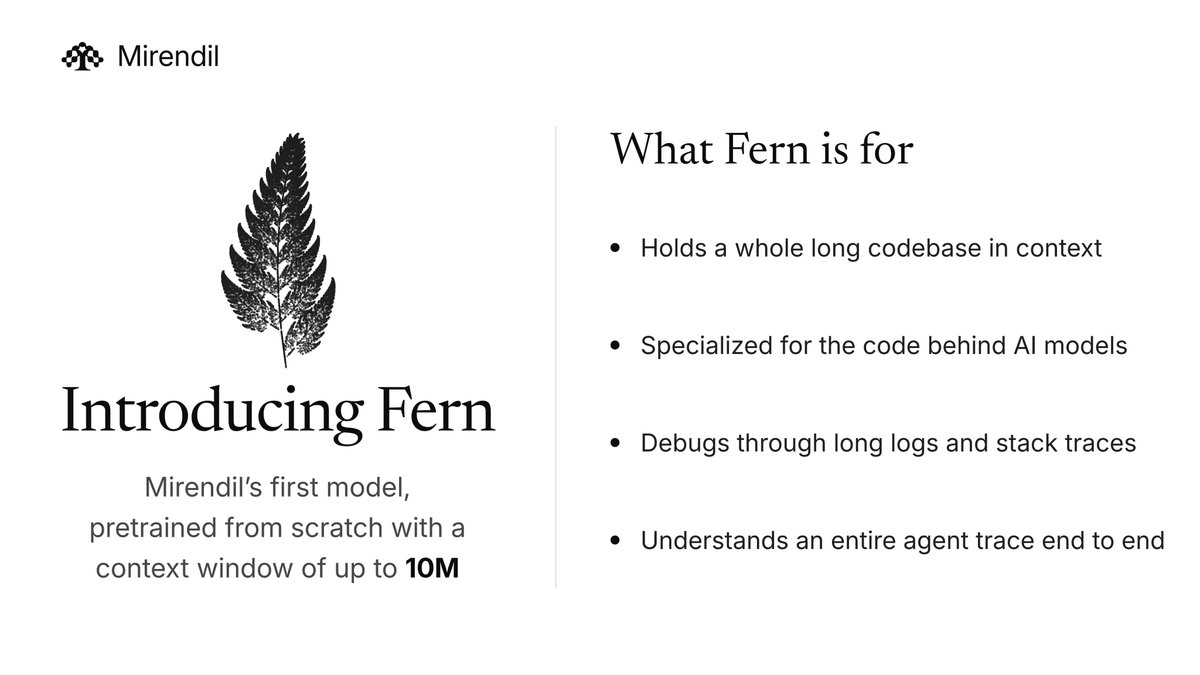
Introducing Fern, Mirendil’s first model: pretrained from scratch, with up to 10M tokens of context! That’s ~0.5M lines of code (roughly Megatron-LM scale) or days of an agent’s work, all in context at once. Its first version, Fern 0.1, had a short round of post-training 🚢
Context
A 10 million token window would let one model read a whole large codebase or days of agent logs at once, roughly ten times what most frontier models advertise. The capability figures come from Mirendil itself, and the model is not yet available to the public.
Mirendil is an AI startup whose cofounder Behnam Neyshabur announced Fern on X at 11:37 AM Eastern on October 26. The company's post says Fern 0.1 is its base model after a short round of post training, and that two larger models are being pretrained. Access is listed as coming soon.
Deep dive
Mirendil announced Fern on October 26, describing it as the company's first model, pretrained from scratch, with a context window of up to 10 million tokens. Behnam Neyshabur, who announced it on X, said that is about half a million lines of code, roughly the size of the Megatron LM library, or days of an agent's work held in context at once.
According to Mirendil's post, Fern's architecture, training and serving were built to support 10 million tokens, about 23 megabytes of code. Neyshabur wrote that the model's predictions keep improving all the way to 10 million tokens. Fern 0.1 is Mirendil's base model after a short round of post training, and the company says new versions will ship frequently.
Mirendil pitches Fern at people who build AI systems: auditing training data for duplicates and benchmark contamination, debugging training runs from long logs, and reading complete agent traces. Coverage of Mirendil's own benchmark table, including CellCog's review, reports strong retrieval at full length, multi hop question answering falling to about 45 percent, and 73.4 percent on SWE Bench Verified, behind leading frontier models on agentic coding.
Neyshabur also wrote that the first pretrained model was built by one researcher in 3.5 months with less than 10 million dollars of compute, and that two larger models are now in pretraining. Baseten posted that Mirendil Base Large had the lowest bits per byte of any model it tested on private codebases. Mirendil has not published a price, an API or model weights.
What to expect next
The next step is access. Mirendil lists Fern as coming soon with an early access form, so independent long context tests will only arrive once outside developers can run it. Watch for third party evaluations of whether the model actually uses all 10 million tokens on real repositories, for pricing given the cost of serving such long inputs, and for the two larger models Neyshabur says are already in pretraining.