Ornith releases Ornith 1.5 122B, an open weights model under the MIT license that it says leads open models of its size

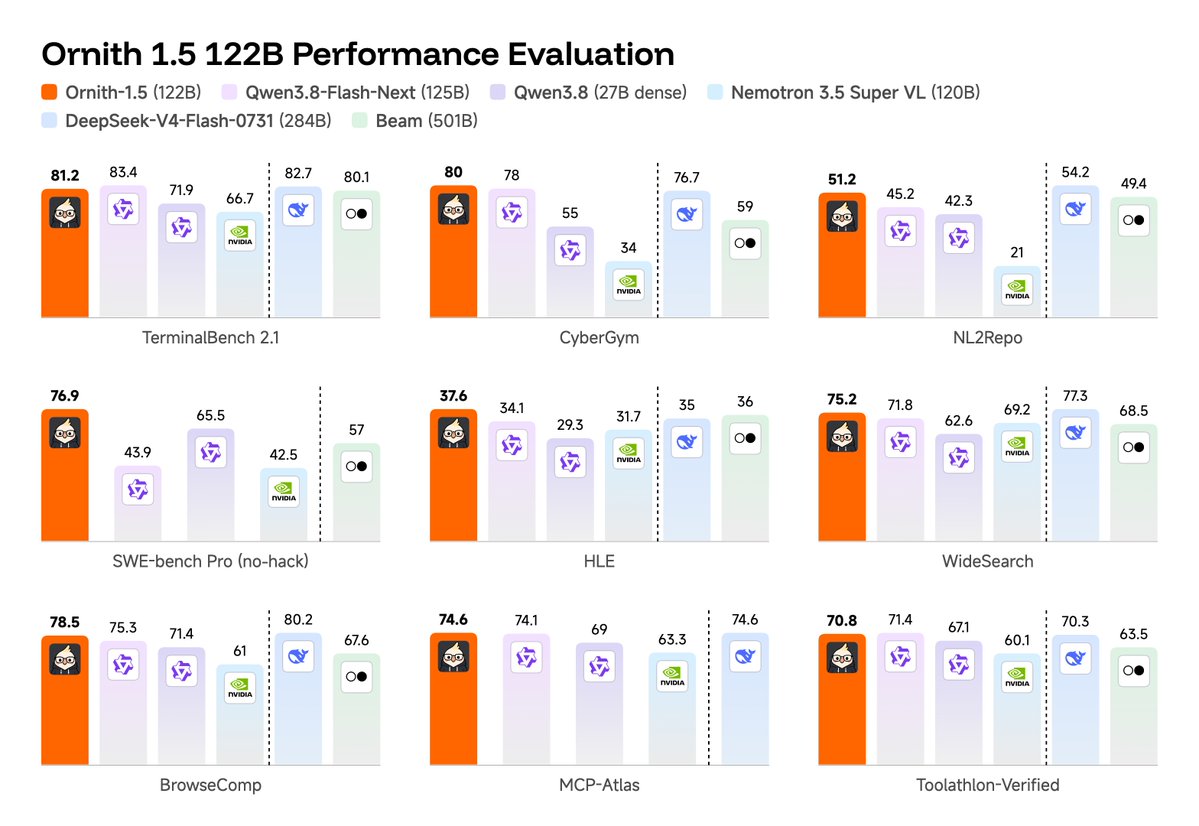
Aloha!🌺 Meet Ornith-1.5-122B: No Tradeoff Between Strong and Fast Stronger. Faster. Leaner. Ornith-1.5-122B delivers frontier-level capabilities with exceptional inference efficiency. With superior instruction following, stronger task decomposition, and deeper understanding of real-world workflows, it achieves state-of-the-art performance among open-source models of comparable size, while running on a single NVIDIA DGX card!! Open weights under the MIT license. Coding ✅SWE-bench Verified: 0.845 ✅TB2.1: 0.813 ✅CyberGym: 0.800 ✅NL2Repo: 0.512 Agentic ✅HLE: 0.446 ✅BrowseComp: 0.785 ✅MCP-Atlas: 0.746 ✅Toolathlon: 0.708 🤗Hugging Face: t.co/w1hD6rra1o We can’t wait to see what you build with Ornith-1.5-122B.
Context
If its self reported scores hold up, developers get a near frontier coding and agent model they can run on a single GPU.
Ornith is a less well known AI lab, and all of the scores here are self reported and have not been checked independently. The model card on Hugging Face describes a 122 billion parameter mixture of experts model, which activates only part of its weights for each token.
Deep dive
On October 20, Ornith announced Ornith 1.5 122B, saying it delivers frontier level capabilities with exceptional inference efficiency and state of the art performance among open source models of comparable size. It released the weights under the MIT license, which allows commercial use.
The post lists self reported scores, including 84.5% on SWE bench Verified, 81.3% on Terminal Bench 2.1, 80% on CyberGym, 44.6% on Humanity's Last Exam, 78.5% on BrowseComp and 74.6% on MCP Atlas. The model card's table gives 81.2 for Terminal Bench 2.1, and lists 48.0 on Humanity's Last Exam with tools and 37.68 without, so the figures in the post do not all match. The card says SWE bench runs used safeguards against reward hacking.
In Ornith's own table, the model beats Qwen3.8 Flash Next, Qwen3.8 27B and Nemotron 3.5 Super VL on most coding and agent tests, but trails DeepSeek V4 Flash 0731, a larger 284 billion parameter model, on Terminal Bench, NL2Repo, BrowseComp and WideSearch. It does not compare against DeepSeek's newer V4.1 Flash 1017.
The post says it runs on a single NVIDIA DGX card. The model card says it serves on a single 80 GB GPU and offers a quantized Mobile version for edge devices. It also says the model handles 262,144 tokens of context, extendable to about 1 million with a scaling technique.
What to expect next
Watch for independent evaluations, from leaderboards such as Artificial Analysis or from developers running the model themselves, which will show whether Ornith's self reported scores hold. Its claim of single GPU serving will be tested as people try the model locally through tools like vLLM, Ollama and llama.cpp, which its model card lists. Also watch for more details on Ornith itself and on how the model was trained, which the post does not explain.