DeepSeek releases V4.1 Flash 1017, an open weights update it says scores higher, finishes tasks faster and writes shorter outputs

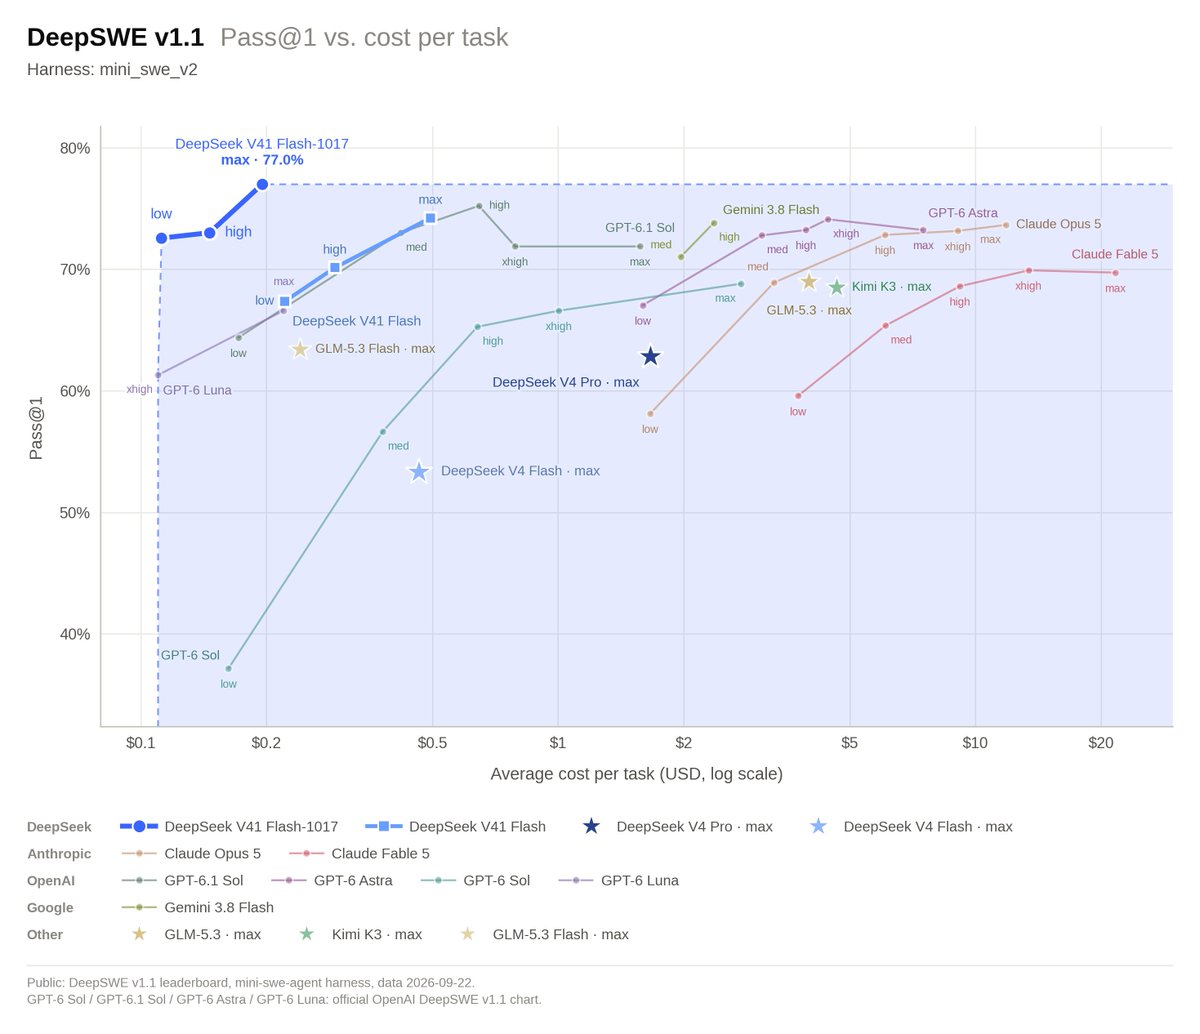
🚀 DeepSeek-V4.1-Flash-1017 is here! Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API. 🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model. 1/4

Context
A stronger and cheaper open model from DeepSeek puts more pressure on paid models from OpenAI, Anthropic and Google, especially for coding agents.
This is a first hand launch thread from DeepSeek, and the benchmark results are its own. The model card describes it as a minor update to V4.1 Flash, released under the MIT license.
Deep dive
On October 17, DeepSeek announced DeepSeek V4.1 Flash 1017. It said the model has stronger benchmark performance, faster task completion and shorter outputs than the previous version, calling it a Pareto improvement in performance and cost, and that it is live on its website, app and API. It said the model is optimized for DeepSeek Harness, Tencent CodeBuddy, WorkBuddy and more.
Later posts in the thread said the model uses reinforcement learning with self feedback to improve end to end project work, and announced an open source release on Hugging Face and ModelScope. DeepSeek also opened its Search and Fetch APIs to everyone, saying they are powered by its own search engine, which serves hundreds of millions of requests a day. Each endpoint costs $0.75 per 1,000 calls, and calls made through server side tools in DeepSeek Harness, Claude Code and Codex are free for DeepSeek API users until billing starts on October 31 at 16:00 UTC.
The DeepSeek Harness account said its 0.2.1 release supports the model, which it said was specifically optimized for the harness during training.
The Hugging Face model card lists 763 billion parameters and a 1 million token context window. DeepSeek's table shows it beating the previous version on every listed test, scoring 77.0 on DeepSWE v1.1 against 74.0 for Claude Opus 5 and 42.3 on Terminal Bench 4.0 against 51.8 for Opus 5.
What to expect next
Watch for independent benchmark results and API price comparisons, since DeepSeek's claims of lower cost per task are its own.
Also watch how quickly hosting providers and coding tools add the open weights, and whether U.S. labs respond with cheaper versions of their own models. Usage of the Search and Fetch APIs after free access ends on October 31 will show whether developers adopt DeepSeek's wider platform, not just its models.