Artificial Analysis Updates Its Coding Agent Index, With Claude Fable 5.2 and Claude Opus 5.5 Tied for First at 58

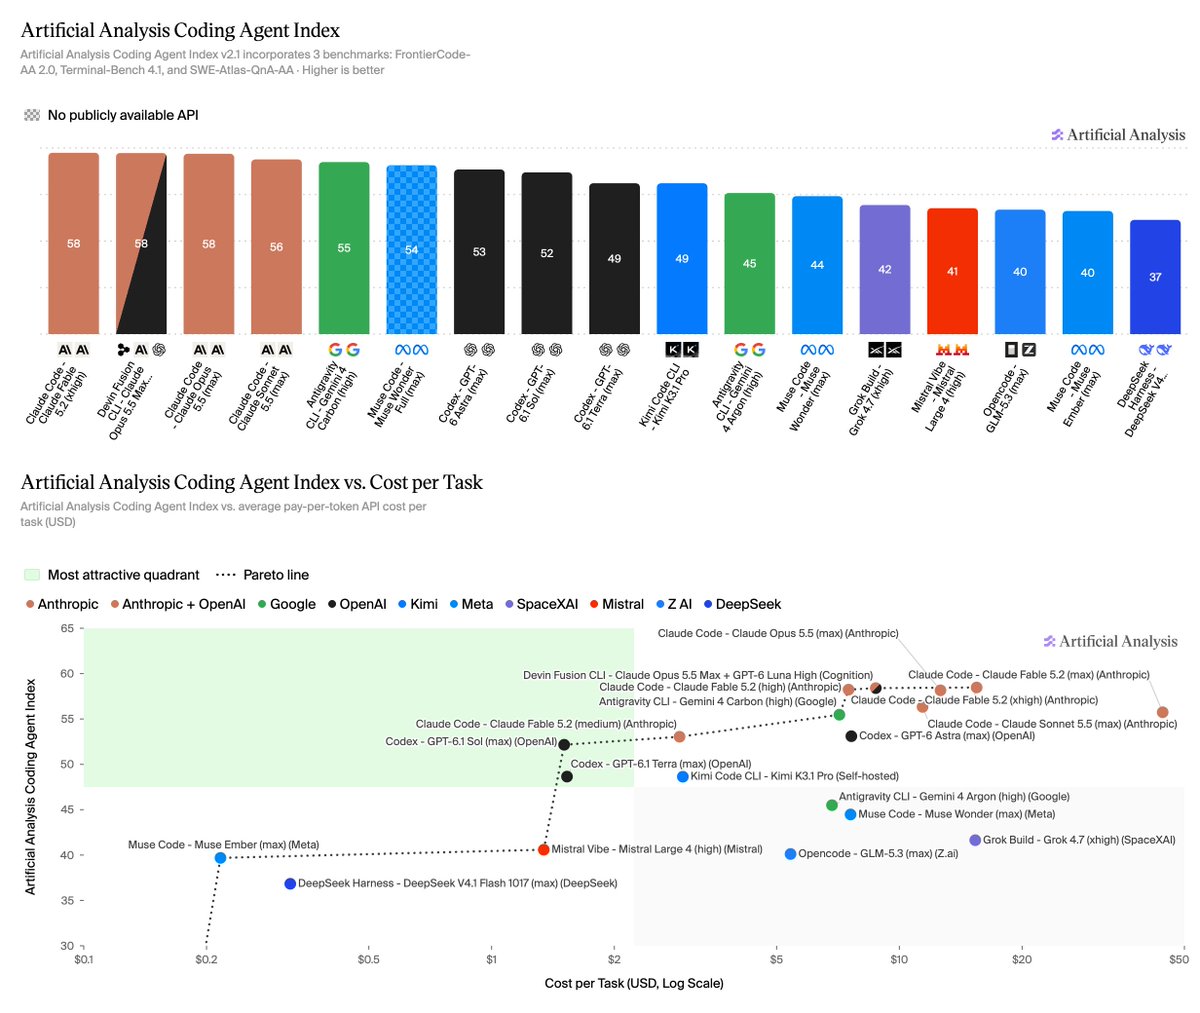
Announcing Artificial Analysis Coding Agent Index v2.1, upgrading FrontierCode and Terminal-Bench. Claude Fable 5.2 and Claude Opus 5.5 share the lead at 58 The Coding Agent Index measures models in agent harnesses; v2.1 of the Index upgrades FrontierCode from 1.1 to 2.0 and
Context
The index scores models inside real coding agents, and a harder repository test cut scores across the board, resetting how buyers compare coding tools.
Artificial Analysis is an independent group that benchmarks AI models and agents. Its Coding Agent Index averages three tests run inside agent harnesses such as Claude Code, Codex and Devin. Version 2.1, announced on November 13, swaps in Cognition's harder FrontierCode 2.0 and an updated Terminal Bench.
Deep dive
Artificial Analysis says version 2.1 of its Coding Agent Index is the equal weight average of three benchmarks covering 322 tasks: FrontierCode AA 2.0, its implementation of Cognition's FrontierCode 2.0 with 132 changes to real open source repositories graded on whether a maintainer would merge them; Terminal Bench 4.1, the same 66 terminal tasks as version 4.0 with updated verifiers meant to improve reliability and resist reward hacking; and SWE Atlas QnA AA, 124 repository question tasks. Each task is run three times.
According to the announcement, Claude Fable 5.2 scores 58 at both xhigh and high effort in Claude Code, and Claude Opus 5.5 at max effort scores 58 in Claude Code and also when paired with GPT 6 Luna High in Cognition's Devin Fusion CLI. Claude Sonnet 5.5 at max effort follows at 56 in Claude Code, and Gemini 4 Carbon at high effort scores 55 in Antigravity CLI.
The group says scores fell by 5 points on average from the previous version, driven by FrontierCode AA 2.0, and that Codex with GPT 6.1 Terra at max effort was the only configuration that did not drop. AlphaSignal reports that all 23 configurations tested on both versions scored lower on the new FrontierCode test, with the mean falling from 45% to 29%.
Artificial Analysis also reports that cost per task varies about 30 times among configurations scoring 48 or more, from $1.51 for Codex with GPT 6.1 Sol to $44.22 for Claude Code with Claude Fable 5.2 at max effort.
What to expect next
Watch whether labs and harness makers respond with new runs, since Artificial Analysis says the index reflects the model and the agent harness together. Because the benchmark mix changed, scores from version 2.1 cannot be compared directly with earlier versions. The wide spread in cost per task among top scorers may matter as much as the ranking for teams choosing a coding agent, and new model releases will be the next test of the tie at the top.