Perplexity Says Gemini 4 Carbon Sets a New Record on Its WANDR Research Benchmark at Lower Cost Than Rivals

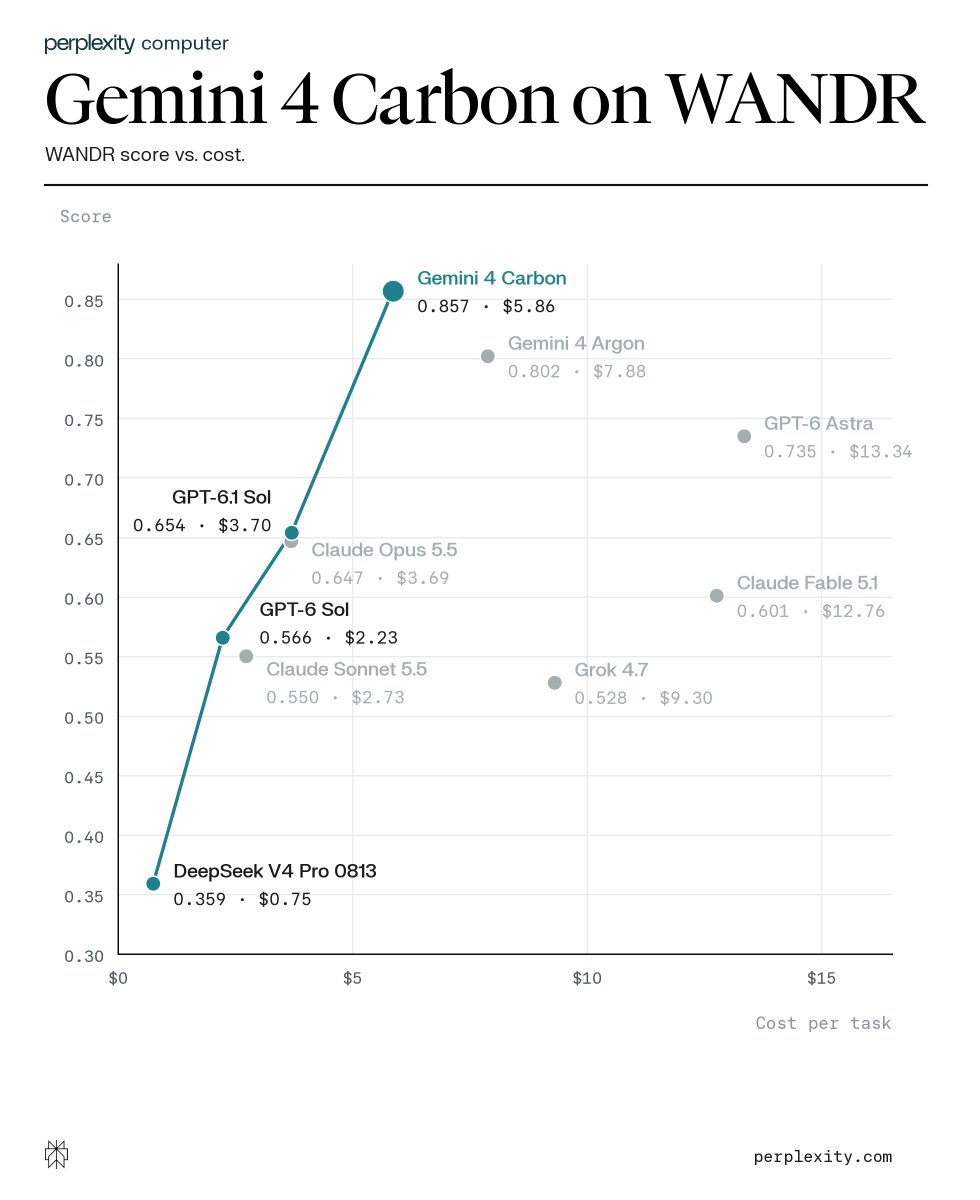
Sharing early evals on Gemini 4 Carbon. Strongest model that we've seen so far for long-form research and answer quality, with a new SoTA on the Wide-And-Deep-Research (WANDR) benchmark. Coming soon to all Perplexity Pro and Max users inside Computer, once we have sufficient token capacity. Congrats @GoogleDeepMind!
Context
If the result holds, Google's newest model would be the strongest option for long research tasks while costing less per task than the top OpenAI and Anthropic models.
Aravind Srinivas is the CEO of Perplexity. WANDR, short for Wide and Deep Research, is a benchmark Perplexity built to test whether AI research agents can find many relevant items and back each claim with evidence. Google DeepMind released Gemini 4 Carbon earlier this week.
Deep dive
Perplexity CEO Aravind Srinivas posted on Friday that early evaluations show Gemini 4 Carbon is the strongest model Perplexity has seen so far for long form research and answer quality, with a new state of the art score on its WANDR benchmark.
The chart he shared puts Gemini 4 Carbon at 0.857 at a cost of 5.86 dollars per task. Next come Gemini 4 Argon at 0.802 for 7.88 dollars, GPT 6 Astra at 0.735 for 13.34 dollars and Claude Fable 5.1 at 0.601 for 12.76 dollars. Grok 4.7 scored 0.528 for 9.30 dollars, and DeepSeek V4 Pro scored 0.359 for 0.75 dollars.
According to OfficeChai, WANDR grades every claim an agent makes against the sources it cites, fetching those pages again to check them, rather than comparing answers to a fixed key. Tasks are modeled on work such as due diligence, market research and literature reviews.
Srinivas said the model is coming to all Perplexity Pro and Max users inside its Computer product once Perplexity has enough token capacity. He gave no date. WANDR was built by Perplexity itself, so these are the company's own numbers and have not been checked independently.
What to expect next
Watch for when Gemini 4 Carbon actually reaches Perplexity Pro and Max users, since Srinivas tied the rollout to token capacity rather than a date. Independent tests on WANDR or similar research benchmarks would show whether the lead holds outside Perplexity's own setup. OpenAI and Anthropic may answer with updates to their own research agents. Pricing per task will matter as much as score for companies running research at scale.