Cognition Says Gemini 4 Carbon Scores 40 Percent on FrontierCode 2.0, Near the Top of Its Coding Benchmark

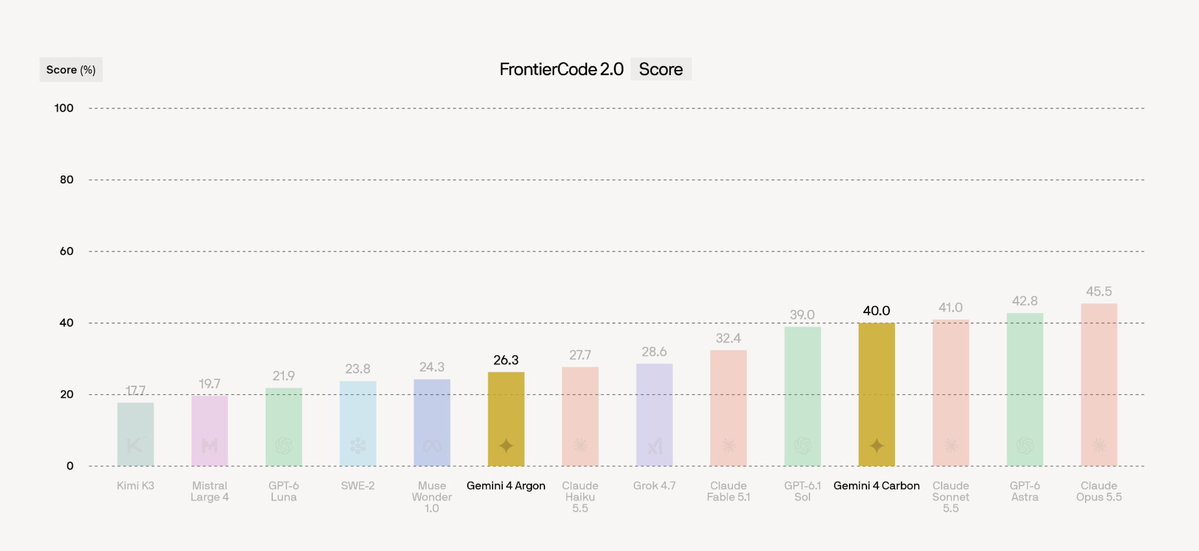
We've evaluated Gemini 4 Carbon and Gemini 4 Argon on FrontierCode 2.0, our coding benchmark that measure's a model's ability to go beyond the spec. Gemini 4 Carbon scores near SOTA with a score of 40% and a cost of $4.04 per task, behind Claude Opus 5.5, GPT-6 Astra, and Claude Sonnet 5.5. Gemini 4 Argon scores 26.3% with a cost of $6.41 per task, ahead of Muse Wonder 1.0, but behind Claude Haiku 5.5 and Grok 4.7. See the leaderboard with full scores:
Context
It is one of the first independent coding results for Google's new Gemini 4 models, placing Carbon close to the best Claude and GPT models at lower cost per task.
Cognition is the company behind the Devin coding agent and the Windsurf editor. FrontierCode 2.0 is its coding benchmark, which it says measures whether a model can go beyond the written spec. Gemini 4 Carbon and Gemini 4 Argon are Google's new models released earlier this week.
Deep dive
Cognition said on Thursday evening that it has evaluated Gemini 4 Carbon and Gemini 4 Argon on FrontierCode 2.0, its coding benchmark that measures a model's ability to go beyond the spec.
According to the post, Gemini 4 Carbon scores near the state of the art at 40 percent, with a cost of 4.04 dollars per task, behind Claude Opus 5.5, GPT 6 Astra and Claude Sonnet 5.5. Gemini 4 Argon scores 26.3 percent at 6.41 dollars per task, ahead of Muse Wonder 1.0 but behind Claude Haiku 5.5 and Grok 4.7.
The chart in the post shows Claude Opus 5.5 leading at 45.5 percent, followed by GPT 6 Astra at 42.8, Claude Sonnet 5.5 at 41.0, Gemini 4 Carbon at 40.0 and GPT 6.1 Sol at 39.0. Lower on the chart are Claude Fable 5.1 at 32.4, Grok 4.7 at 28.6 and Kimi K3 at 17.7.
The results come from a single benchmark built by a company that sells coding agents, so they reflect Cognition's tasks and harness. Still, they suggest Google's new top model is competitive with the leaders on hard coding work. Argon costing more per task than Carbon while scoring lower is notable and was not explained in the post.
What to expect next
Watch for more independent coding evaluations of Gemini 4, such as SWE style benchmarks and arena rankings, to see whether Cognition's results hold. Developers will compare real world cost and speed in tools like Antigravity and Cursor. Google may also update the models quickly, so scores could shift within weeks. Cognition may also add more models to the leaderboard, including any new releases from OpenAI and xAI expected in the coming weeks.