Hidden Model Named Obsidian 3 Spotted at Number One in Cognition's FrontierCode 2.0 Data Ahead of Claude Opus 5.5

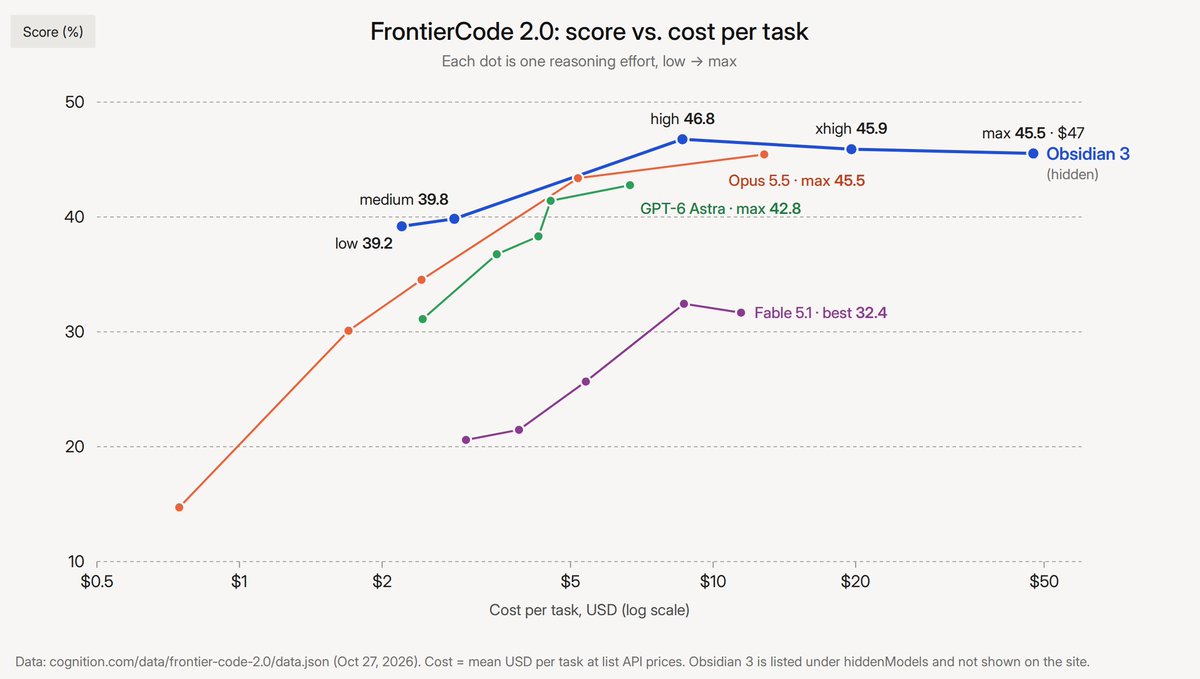
Very likely Fable 5.5 found in FrontierCode 2.0: Cognitions data reveals a hidden model, "Obsidian 3," scoring 46.8% against #1 Opus 5.5’s 45.5%, and since it runs in the claude-code harness used exclusively by Claude models, its save to say its Fable 5.5.
Context
Because Obsidian 3 runs inside the claude code harness reserved for Anthropic models and peaks at 46.8 percent against first place Claude Opus 5.5 at 45.5 percent, the benchmark file points to an unannounced frontier Anthropic coding model already undergoing external evaluation.
Cognition released its FrontierCode 2.0 software engineering benchmark on October 27, ranking Claude Opus 5.5 first on its public leaderboard at 45.5 percent ahead of GPT 6 Astra at 42.8 percent. Developers inspecting the public JSON data file behind the leaderboard discovered an unannounced entry named Obsidian 3 inside the hiddenModels array that outperforms every publicly listed model.
Deep dive
Developers inspecting the underlying JSON dataset for Cognition's newly launched FrontierCode 2.0 benchmark uncovered a hidden model entry named Obsidian 3 that achieves the highest score on the entire evaluation. While Cognition's public leaderboard lists Anthropic's Claude Opus 5.5 in first place with a maximum score of 45.5 percent and OpenAI's GPT 6 Astra second at 42.8 percent, the raw data file at cognition.com includes Obsidian 3 under a hiddenModels array.
According to the benchmark data plotted by @tensorson and highlighted on Wednesday morning by @kimmonismus, Obsidian 3 starts at a score of 39.2 percent at low reasoning effort for roughly 2.50 dollars per task, climbs to a peak score of 46.8 percent at high effort for roughly 8 dollars per task, and records 45.9 percent at extra high effort and 45.5 percent at maximum effort costing 47 dollars per task. By comparison, Claude Opus 5.5 reaches its 45.5 percent peak at maximum effort for roughly 12 dollars per task, while Anthropic's faster Fable 5.1 model tops out at 32.4 percent for about 8 dollars per task.
Crucially, the JSON metadata shows that Obsidian 3 was evaluated inside the claude code agent harness, which Cognition uses exclusively for Anthropic models in the benchmark. Because Obsidian 3 outperforms Claude Opus 5.5 at high reasoning effort while costing about 8 dollars per task at that point, researchers and developers on X speculated that Obsidian 3 is either an upcoming Fable 5.5 release or an internal next generation Claude checkpoint undergoing pre release testing with partner labs.
What to expect next
Benchmark data leaks inside public JSON files have repeatedly telegraphed major frontier model launches days before official announcements. Because Obsidian 3 runs inside the Claude Code harness and beats Claude Opus 5.5 at high effort for roughly eight dollars per task, watch whether Cognition updates its hiddenModels array or whether Anthropic officially unveils Fable 5.5 or a new Claude checkpoint to extend its software engineering lead.