Artificial Analysis Launches Intelligence Index v5 Built Mostly on Private Tests, With Claude Opus 5.5 First and Open Weights Models Falling 12 Points Behind

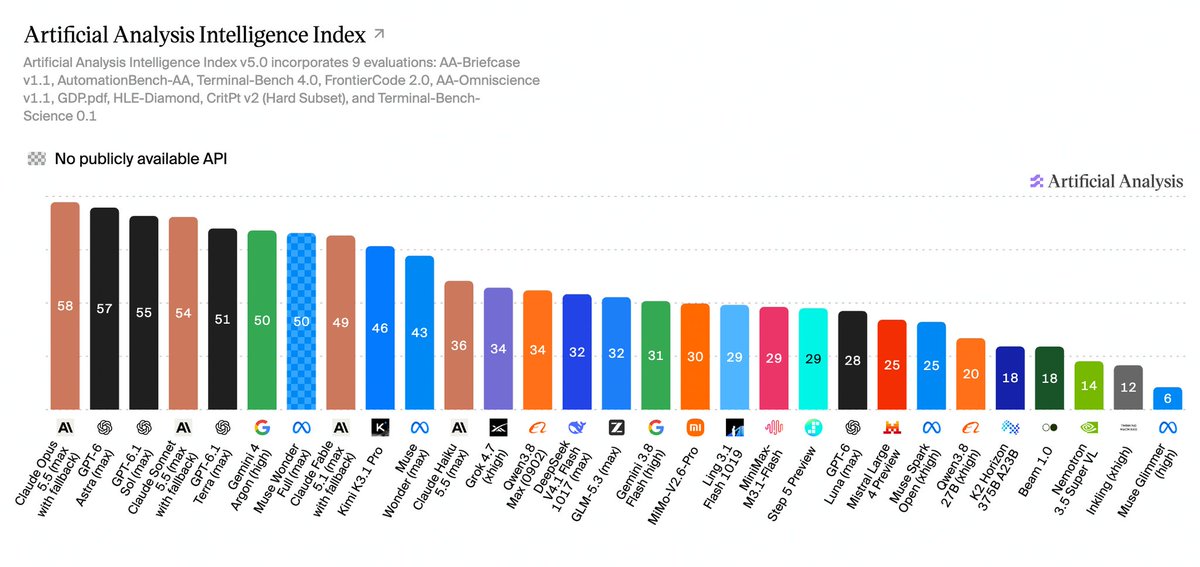
Announcing Artificial Analysis Intelligence Index v5, featuring 2 new benchmarks and 3 upgrades. For the first time, the majority of the Index is built on private datasets The Artificial Analysis Intelligence Index is our composite measure of model capabilities across tasks reflecting real-world usage today. v5 is our biggest upgrade since v4 launched in January. With v5, 60% of the Index is now based on evaluations with private test sets or held-out answers. Alongside Intelligence Index v5, we’re launching the Artificial Analysis Progress Index v1, which tracks model capability over time on one continuous scale. New to the Intelligence Index: ➤ FrontierCode 2.0: Cognition's newly-launched private benchmark of real-world coding tasks, graded on whether a repository maintainer would merge the agent's change ➤ Terminal-Bench-Science: 70 agentic scientific research tasks, run in a terminal environment Upgraded: ➤ HLE-Diamond (replacing Humanity's Last Exam): a refined 1,000-question version of Humanity's Last Exam, split evenly between reasoning and knowledge questions ➤ AA-Omniscience v1.1: An updated dataset with saturated and public set questions removed, new questions added, and ambiguous or erroneous questions revised ➤ CritPt v2: a private, 40-question hard subset of CritPt v2, revised by the CritPt authors and run with a code-execution tool Staying in the Index: AA-Briefcase, AutomationBench-AA, GDP.pdf and Terminal-Bench 4.0 Removed from the Index: GDPval-AA v2.1, SciCode, and AA-LCR v1.1 Key results: ➤ Claude Opus 5.5 (max) leads at 58, ahead of GPT-6 Astra (max, 57) and GPT-6.1 Sol (max, 55): Anthropic and OpenAI hold the top five models. Gemini 4 Argon (high) is next at 50 ➤ The open weights gap widens from 3 points to 12: Kimi K3.1 Pro (weights not yet released) is the top open weights model at 46. Among released weights, DeepSeek V4.1 Flash 1017 (max) and GLM-5.3 (max) lead at 32 - 26 points behind the leader and below Claude Haiku 5.5 (max, 36) ➤ Cost per task varies by more than 13x among the leading models: of the 10 highest-scoring models shown, GPT-6.1 Terra (max) is the cheapest at $0.96 per Intelligence Index task and Claude Fable 5.1 (max) the most expensive at $13.04
Context
The Artificial Analysis index is one of the most cited independent leaderboards for comparing AI models, and moving most of it onto private test sets makes it harder for labs to tune for the benchmark while showing a much wider gap between closed and open models.
Artificial Analysis is an independent firm that benchmarks AI models and publishes a composite Intelligence Index, last overhauled with v4 in January. Version 5 adds Cognition's FrontierCode 2.0, launched the same day, and a new Terminal Bench Science suite of agentic research tasks. The firm also launched a Progress Index v1 that tracks model capability over time on one scale.
Deep dive
Artificial Analysis announced version 5 of its Intelligence Index, which it calls its biggest upgrade since v4 launched in January. For the first time most of the index rests on private data: the firm says 60 percent of the score now comes from evaluations with private test sets or held out answers, which limits how much a lab can benefit from training on public benchmark questions.
The index now combines nine evaluations. New additions are FrontierCode 2.0, Cognition's private benchmark that grades coding agents on whether a repository maintainer would merge their change, and Terminal Bench Science, 70 agentic scientific research tasks run in a terminal. Upgraded entries include HLE Diamond, a refined 1,000 question version of Humanity's Last Exam, AA Omniscience v1.1 and a private 40 question hard subset of CritPt v2. GDPval AA v2.1, SciCode and AA LCR v1.1 were removed.
On the new scale, Claude Opus 5.5 at max effort leads with 58, ahead of GPT 6 Astra at 57 and GPT 6.1 Sol at 55, so Anthropic and OpenAI hold the top five places. Gemini 4 Argon at high effort comes next at 50. The firm says the open weights gap widened from 3 points in v4.3 to 12 points. Kimi K3.1 Pro, whose weights are not yet released, scores 46, while the best models with released weights, DeepSeek V4.1 Flash 1017 and GLM 5.3, score 32, below Claude Haiku 5.5 at 36.
Cost varies widely too. Among the ten highest scoring models, Artificial Analysis says GPT 6.1 Terra is the cheapest at 0.96 dollars per index task and Claude Fable 5.1 the most expensive at 13.04 dollars.
What to expect next
Labs often quote Artificial Analysis scores in launch posts, so expect upcoming releases, especially from open weights developers such as Moonshot, DeepSeek and Zhipu, to be measured against the v5 numbers. The big question is whether the 12 point gap shrinks once Kimi K3.1 Pro weights ship. The new Progress Index should also make it easier to track how quickly the frontier moves from month to month.