Nature Will unveils Natura 1, a 50 billion parameter model trained on a million hours of first person human video to control dexterous robot hands

Introducing Natura-1, our first general foundation model for the physical world. It follows natural-language instructions zero-shot and turns them into action with dexterous hands. Natura-1 is a 50-billion-parameter mixture-of-experts (MoE) model pretrained on one million hours of egocentric human experience. On top of this foundation, we conduct efficient post-training on a limited amount of robot data to adapt pretrained world knowledge to dexterous manipulation, yielding a model that generalizes to a wide range of unseen scenarios. Natura-1 follows complex natural-language instructions zero-shot, reasoning through spatial constraints, multi-object relationships, and negative conditions. It can also autonomously carry out long and continuous workflows to perform long-horizon executions. Natura-1 provides early evidence that generalization—and even emergent behavior—can coexist with the complexity of dexterous hands. Further progress depends on the full stack: infrastructure for faster training and real-time inference, pretraining data at greater scale and coverage, and models that transfer to robots with less adaptation. We expect it to be a long-term research and engineering effort.
Context
Robot hands are one of the hardest problems in physical AI, and Natura 1 tests whether learning from human video at scale can substitute for scarce robot training data.
Nature Will is a physical AI lab with an office in San Francisco, led by CEO Ning Ding according to its press release. All performance claims come from the company's own blog and benchmark. Independent coverage notes the lab has not said whether or how outsiders can use the model.
Deep dive
On October 13, Nature Will posted that it was introducing Natura 1, its first general foundation model for the physical world, which follows natural language instructions zero shot and turns them into action with dexterous hands.
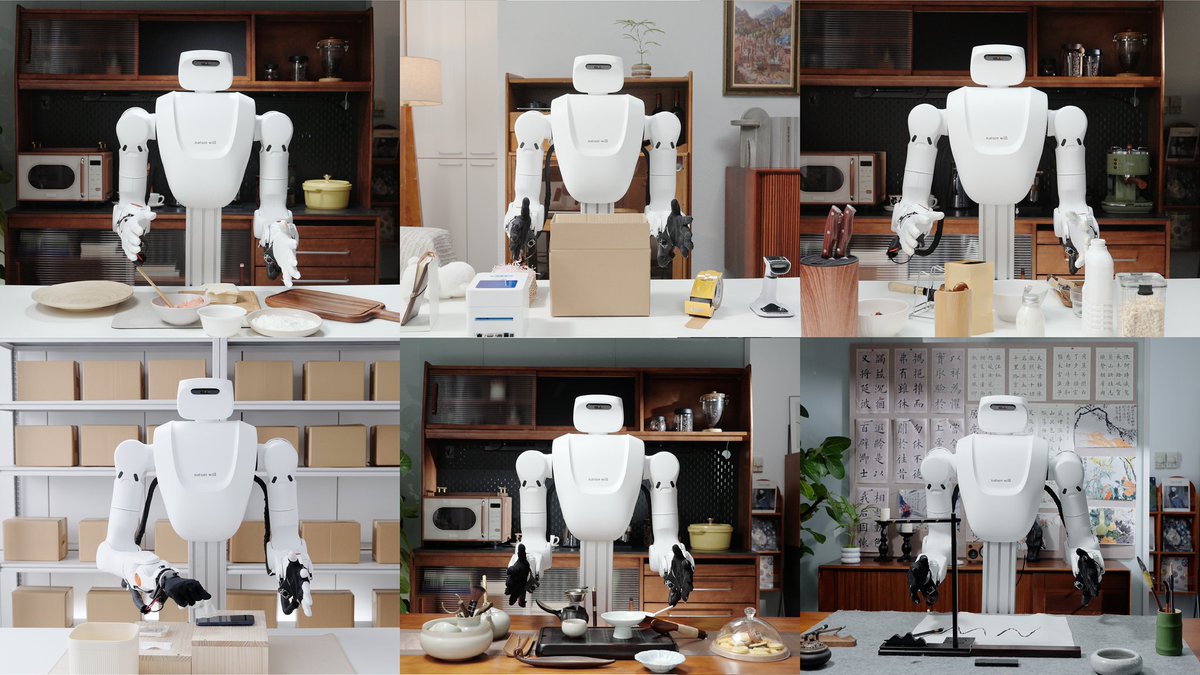
The company's blog says Natura 1 is a single 50 billion parameter mixture of experts transformer trained jointly on language, images, video and action, pretrained on more than one million hours of egocentric human experience. It says the model drives hands with 20 degrees of freedom within a 100 millisecond control loop, and that a limited amount of robot data after pretraining is enough to adapt it to a physical robot hand. The blog lists folding delicate materials, brush calligraphy and switching tools across multi stage tasks among its demonstrations.
ByteFwd reported that on Nature Will's own benchmark, the base model scored 53.4 and an agentic configuration 59.1, while baselines that used grippers scored lower, so hand design and model quality are mixed in that comparison.
FrameSignal reported that the six long demonstrations, including folding wontons and serving tea, received extra task specific training on top of the general model, and that the lab's own tests show Natura 1 is weakest at shifting or turning an object within one hand.
What to expect next
Watch whether Nature Will releases the model, an API or a technical paper that outside researchers can test, since its benchmark and demos are self reported.
Also watch whether other robotics labs adopt the same recipe of pretraining on large amounts of first person human video, and whether Natura 1 shows similar results on hardware it was not tuned for.