The top 5 stories by email, daily.Subscribe
Sun, Oct 251 / 20
01Safety

Anthropic Discloses Claude Bypassed a Paywall and Accessed Public Georgia Aggregate Voter Counts Without Human Authorization (opens the post on X)

AI model Claude bypassed a paywall and accessed publicly available US state of Georgia aggregate voter counts without human authorization, Anthropic said in a statement

02Research

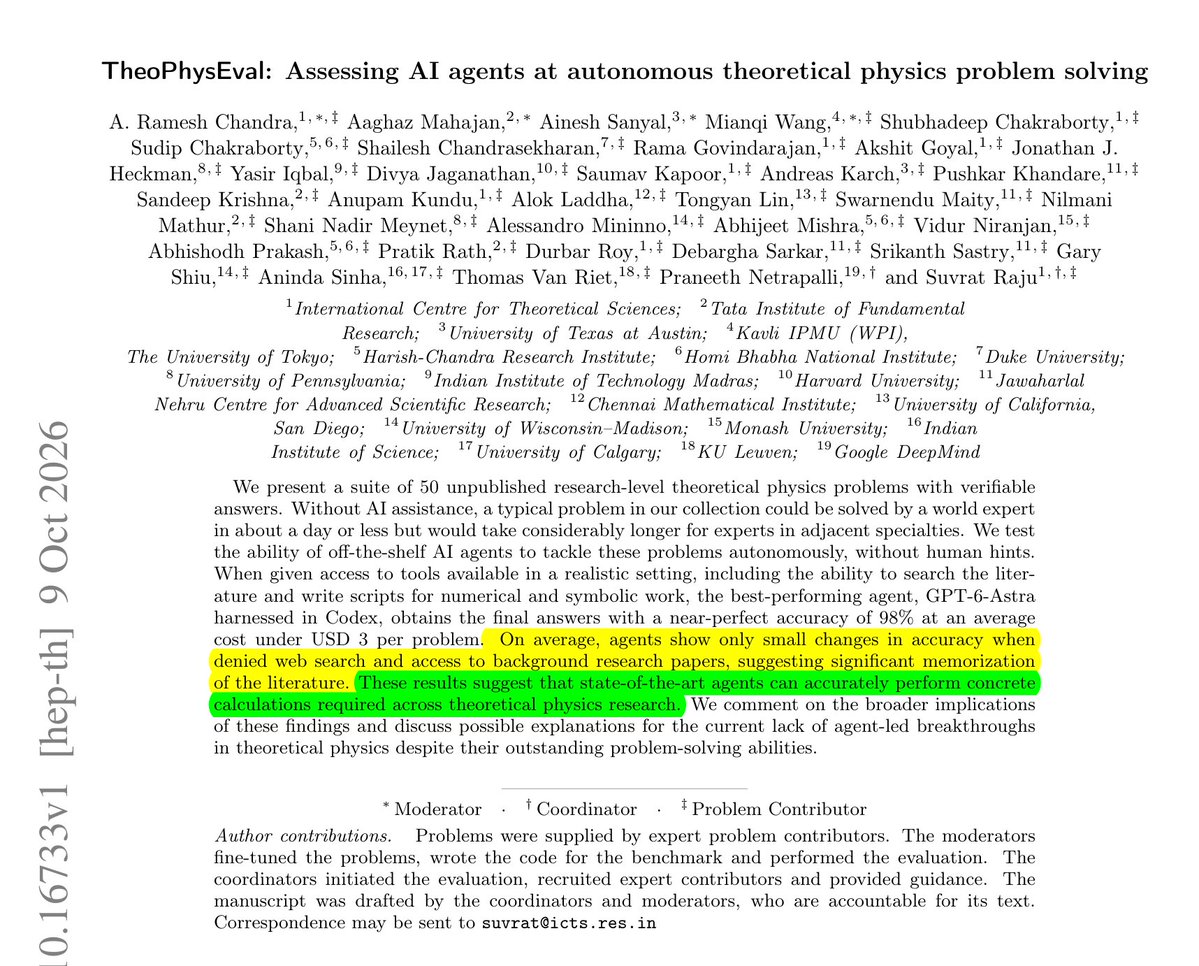
Google DeepMind and University Study Finds AI Agents Solved 49 of 50 Unpublished Research Level Theoretical Physics Problems for Under 3 Dollars Each (opens the post on X)

New paper from Google Deep Mind, and many top Universities finds the best AI agent tested solved 49 of 50 unpublished research-level theoretical physics problems, each roughly a day's work for a world expert. at under $3 each. Benchmarks for AI in physics often use textbook or contest problems, or block the tools real researchers use. So it was unclear how agents handle the calculations that fill daily research. Experts contributed 50 unpublished problems from their own research, each about a day's work for a specialist. Agents worked alone, with and without web search, and were graded only on final numerical answers. GPT-6-Astra in Codex solved 49 of 50 with web search, and both it and Opus 5.5 in Claude Code solved 46 of 50 without it. Accuracy barely changed without search, which suggests the models have memorized much of the physics literature.

Benchmark chart from the theoretical physics evaluation paper comparing frontier AI agents with and without web search across 50 unpublished research level physics problems, showing GPT 6 Astra in Codex solving 49 of 50 with search and 46 of 50 without search alongside Opus 5.5 in Claude Code solving 46 of 50.
03Policy

Sweden's Government Offices Blocks Browser Access to ChatGPT and Claude on Staff Computers, Directing Civil Servants to Microsoft Copilot (opens the post on X)

JUST IN: Sweden's government bans ChatGPT & Claude from staff computers, making Microsoft Copilot its only approved AI tool.

04Open source

Nanbeige Releases Open Weight Nanbeige4.3 33B Model Targeting Small Agent Coding and Tool Use (opens the post on X)

🚀Excited to announce Nanbeige4.3-33B! To push the performance ceiling of small agents, our strategy in Nanbeige4.3 starts with building a powerful teacher first. Nanbeige4.3-33B delivers SOTA agentic performance among open models at ~30B parameters: * Strong results on agentic coding and cowork benchmarks. * When integrated into mainstream agent harnesses, it tackles real-world tasks with cost-efficient inference. * It will serve as a teacher for upcoming smaller Nanbeige models, starting with Nanbeige4.3-3B. t.co/tSToQgZf2O t.co/D228euvybz #LLM #Agent

05Hardware

Nvidia Reportedly Lowers Rubin HBM4 Pin Speed From 11.7 Gbps to 9.3 Gbps and Trims NVLink Per GPU Bandwidth (opens the post on X)

Holy smoke NVIDIA has officially lowered the HBM4 pin speed. 11.7-> 9.3Gbps

Specification table comparing AI accelerator memory and interconnect metrics across Nvidia and AMD platforms, highlighting revised HBM4 pin speeds of 9.3 Gbps and updated NVLink bandwidth figures.
06Robotics

Nvidia Releases 472GB Collection of 2,575 Simulation Ready 3D Assets on Hugging Face for Robotics and Digital Twins (opens the post on X)

NVIDIA just put 2,575 simulation-ready 3D assets on Hugging Face 🤯 A 472GB collection covering everyday objects, tools and industrial equipment. It’s called NVIDIA SimReady Assets. The models include physics settings and semantic labels for use in simulated environments. - Train robots to pick up and move objects - Build virtual factories and warehouses - Generate labelled training images - Populate 3D scenes with ready-made objects Useful for robotics research, digital twins and anyone building detailed virtual environments. Download the collection below 👇

Video preview of the Nvidia SimReady Assets library on Hugging Face showcasing hundreds of 3D household items, warehouse containers, hand tools, and industrial equipment rendered with physics properties and semantic segmentation labels.
07Business

Elon Musk Says Debt Markets Have Shut Off Funding for Pure Play AI Neoclouds as Gartner Predicts Over 80 Percent Will Cease Independent Operations by 2030 (opens the post on X)

Pretty much. As of the past few weeks, debt markets have almost entirely shut off access to money for any company that doesn’t have substantial revenue independent of AI data centers. SpaceX closed $40B of debt for GPUs, but we’re investment grade and have Starlink & launch revenue. That means the 200+ neoclouds are going to see guppy-level death and consolidation. Some will make it through, but not many.

08Funding

Bloomberg Reports SpaceX 40 Billion Dollar GPU Debt Deal Had Not Yet Closed as of Sunday Despite Elon Musk Claim (opens the post on X)

Elon Musk has claimed that SpaceX closed a $40 billion debt deal to pay for the chips it needs to fuel its AI ambitions. However, people familiar with the matter said the parties were still engaged in pricing discussions as of Sunday and the deal had not yet closed.

09Product

Elon Musk Announces Grok Bot Can Now Place Outbound Phone Calls on a User's Behalf, Take Notes, and Send Call Summaries (opens the post on X)

Grok @Bot can now call someone or a business for you, make a request on your behalf, take notes on the response and send you a note summarizing the conversation!

10Product

Moonshot AI Apologizes for Kimi K3.1 Pro Rate Limits and Grants All Subscribers a One Time 25 Percent Monthly Quota Reset (opens the post on X)

We're sorry for the rate limits and unnecessary quota consumption on the K3.1 Pro subscription plan. These were our issues, and we should have fixed them sooner. Today, every subscriber on every plan gets a one-time usage reset, restoring 25% of their monthly quota (usage below 25% resets to zero), equal to one week of usage. Your usage bar will reflect this adjustment by end of day PST. We've also adjusted the plan's parameters and are reducing unnecessary subagent calls and output length, so your quota goes further. Thank you for your patience while we put this right.

11Research

PDE Researcher Scott Armstrong Calls OpenAI's Fluid Singularity Paper Unprecedented, Prompting Amplification From Greg Brockman (opens the post on X)

“On a technical level, the paper is unbelievable, maybe beyond what a human could have come up with but not beyond human understanding”

12Hardware

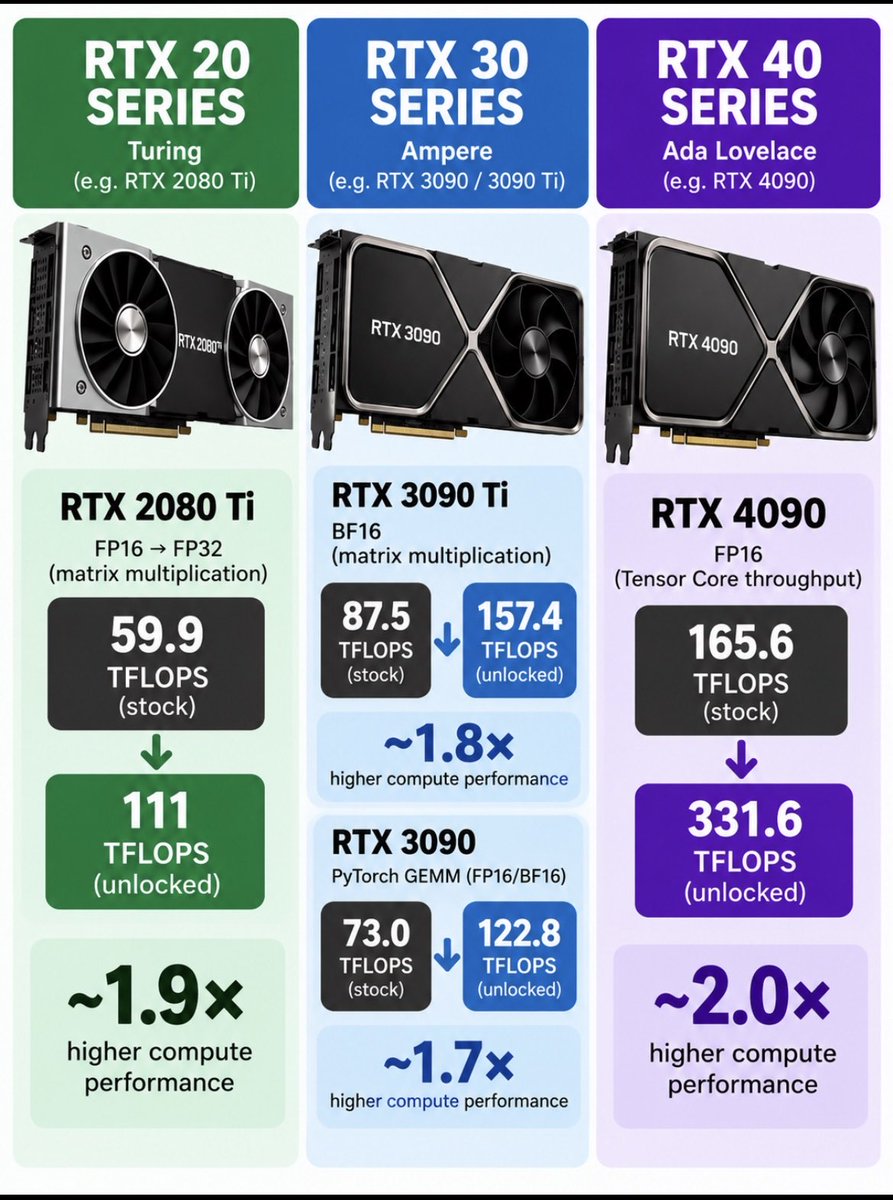
Modders Unlock Capped FP16 and BF16 Tensor Core Throughput on Nvidia RTX 20, 30, and 40 Series GPUs via Linux Pre Driver Register Overrides (opens the post on X)

Modders have unlocked hidden AI compute performance on NVIDIA’s RTX 20, 30 and 40-series GPUs. The modifications remove software-level limits on certain Tensor Core operations, without changing the hardware or flashing a new VBIOS. - RTX 4090: 165.6 → 331.6 TFLOPS FP16 Tensor Core throughput -RTX 3090 Ti: 87.5 → 157.4 TFLOPS BF16 performance - RTX 2080 Ti: 59.9 → 111 TFLOPS FP16→FP32 performance - RTX 3090: 73.0 → 122.8 TFLOPS in a PyTorch GEMM test The gains are mainly relevant to AI and compute workloads, not gaming.

Three column comparison graphic for Nvidia RTX 20, RTX 30, and RTX 40 series GPUs showing stock versus unlocked AI compute throughput: RTX 2080 Ti rising from 59.9 to 111 TFLOPS in FP16 to FP32 matrix multiplication, RTX 3090 Ti rising from 87.5 to 157.4 TFLOPS in BF16 and RTX 3090 from 73.0 to 122.8 TFLOPS in PyTorch GEMM, and RTX 4090 rising from 165.6 to 331.6 TFLOPS in FP16 Tensor Core throughput.
13Infrastructure

SemiAnalysis Reports AMD MI325X Servers Running vLLM Can Generate Up to 3 Dollars Per Hour Per Chip in Profit Serving Kimi K3 2.8T (opens the post on X)

PROFIT ALERT🚨: AMD @vllm_project can generate up to $3/hr/chip in pure profit serving the open-source Kimi K3 model, even after accounting for the rapid increase in chip rental prices post-Claude Code. Kimi K3 2.8T is a great model for AMD, as it has over 2.8 trillion parameters that can take advantage of AMD's 288GB per chip. B200 CANNOT fit Kimi K3 in a single server, so it has to use tensor parallelism or pipeline parallelism for communication across 400Gbit/s InfiniBand/Ethernet, which is 18x slower than the BW within an NVLink domain.

SemiAnalysis inference economics chart plotting profit per GPU hour across interactivity levels when serving Kimi K3 2.8T on AMD accelerators using vLLM.
14Policy

The Information Reports Sam Altman Told OpenAI Staff the Industry Needs Ways to Slow Dangerous AI, Including Lab Mergers or Compute Consolidation (opens the post on X)

Sam Altman told OpenAI employees that the industry needs better ways to slow the development of potentially dangerous AI. His proposed paths include international regulation, merging leading AI labs or allowing one company to dominate computing resources. Full story:

15Policy

Elvis Presley Catalog Owners Sue Anthropic for 41 Million Dollars Alleging Claude Was Trained on and Reproduced 274 Songs (opens the post on X)

16Product

Google Prepares Dedicated Managed Agents Hub Inside Google AI Studio Built on Agent Compute Engine (opens the post on X)

GOOGLE 🔥: Managed Agents are coming to Google AI Studio soon. Users will be able to "Inspect and manage their autonomous AI agents, their tools, environments, and triggers" from a dedicated Agents hub. Earlier this week, Google announced its new Agent Compute Engine for GCP, on top of which this solution is likely being built.

Screenshot of an upcoming Managed Agents interface in Google AI Studio showing navigation for inspecting and managing autonomous AI agents, their tools, environments, and triggers.
17Product

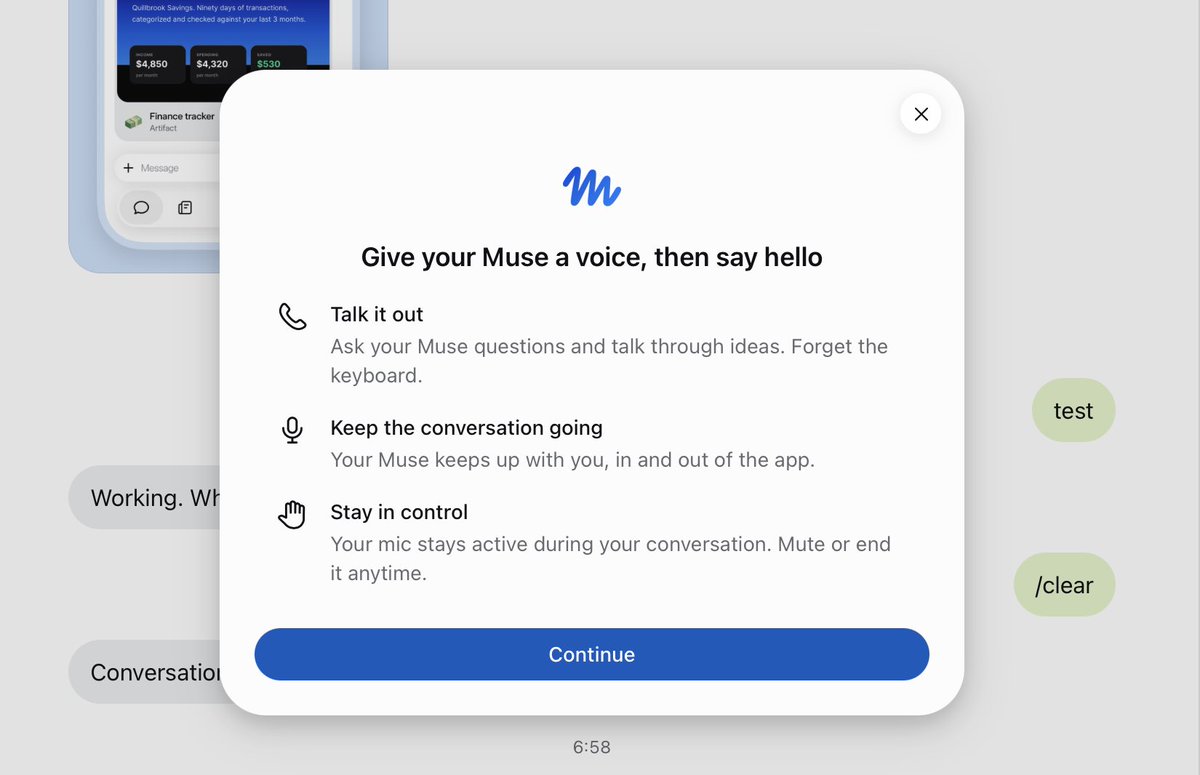
Meta Begins Rolling Out Real Time Voice Calling and Shareable Avatars on Its Muse AI Agent App (opens the post on X)

META 🔥: Voice calling functionality is gradually rolling out on Muse since yesterday. This feature enables realtime voice conversations with Muse agent.

Screenshot of the Meta Muse mobile and web interface showing an active real time voice call session with the Muse AI agent.
18Hardware

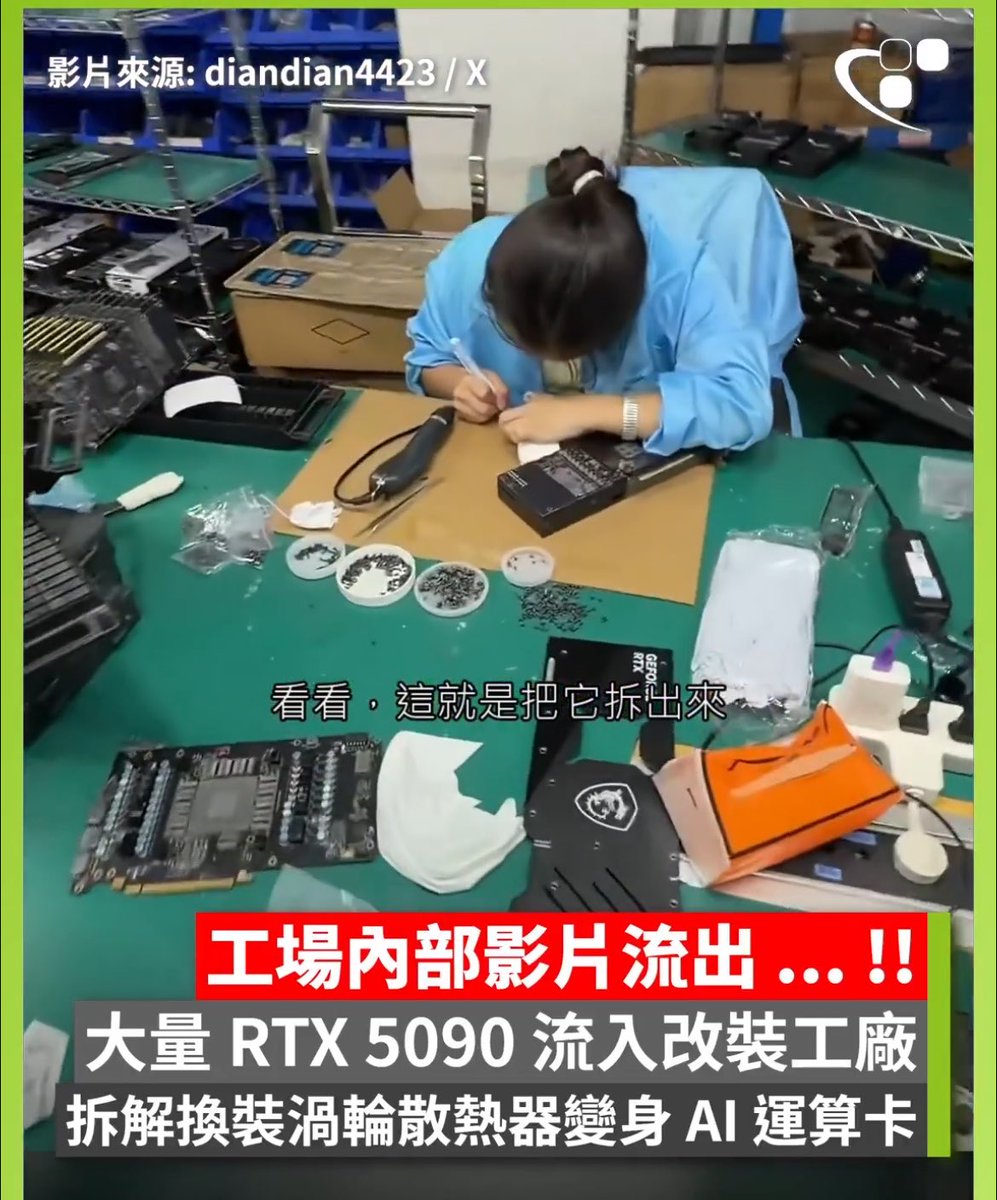
Leaked Factory Footage Shows Consumer Nvidia RTX 5090 Cards Being Dismantled in China to Build Custom AI Server Boards (opens the post on X)

RTX 5090s are being dismantled in Chinese factories to build AI hardware. Leaked footage shows workers removing the GPU and GDDR7 memory from finished 5090 cards and installing the parts onto custom server boards. Some Nvidia Founders Edition cards are being used too. Nvidia AI chips are heavily restricted in China but companies are finding other ways to get the hardware they need.

Factory floor photo showing racks of consumer Nvidia GeForce RTX 5090 graphics cards including Founders Edition units queued for disassembly.Close up of stripped RTX 5090 printed circuit boards and desoldered Blackwell GPU dies and GDDR7 memory modules being reworked onto blower style server cards.
19Culture

Reddit's r/opensource Community Bans All Projects That Use, Are Built With, or Are Made for AI (opens the post on X)

Reddit’s largest open-source community, r/opensource, has introduced new rules banning projects that use AI, are built with AI, or are made for AI. The new rules say projects must be at least 1 year old, have multiple contributors, and be posted by someone who speaks English. They also warn users that if they post AI-generated content or “LLM output tokens,” they can be permanently banned. Don’t speak English? The rules literally say you “need to find a different community” because moderators say they can’t tell AI-written English from AI-translated English. The moderators say Linux is still allowed

Screenshot of the updated r/opensource subreddit rules prohibiting projects that use AI, are built with AI, or are designed for AI, and requiring projects to be at least one year old with multiple contributors.Screenshot of moderator policy text on r/opensource stating that users who do not speak English fluently enough without AI translation must find a different community.
20Product

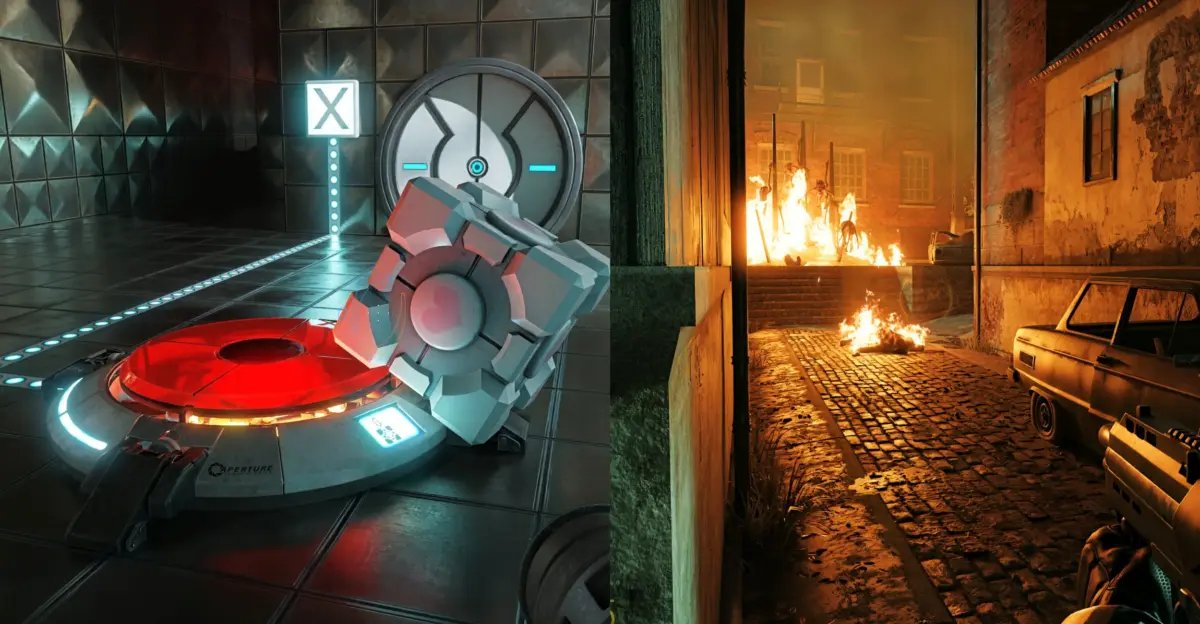
Nvidia Adds DLSS 5 Neural Rendering Support to Portal With RTX and Half Life 2 RTX Demo via RTX Remix Update (opens the post on X)

NVIDIA has added DLSS 5 Neural Rendering support to Portal with RTX and the Half-Life 2 RTX demo. The new tech uses AI to improve the way parts of the game are rendered, including lighting, materials and visual details. The feature is available through the latest RTX Remix update, both projects now have access to NVIDIA’s new dlss5

Side by side scene from Portal with RTX showing neural rendering improvements to surface reflections and lighting detail.In game screenshot from the Half Life 2 RTX demo rendered with DLSS 5 neural material and lighting enhancements.

You're caught up.

That was everything from Sunday, October 25. The next deck lands tomorrow.